
Corporate Data Engineering Training Courses
Pipelines your business can trust.
We build data engineering capability inside organizations: the pipelines, platforms, and practices that turn raw data into reliable analytics and AI. Instructor-led programs across Spark, ETL, streaming, and cloud data platforms are how we do it, scoped to your stack and delivered wherever your teams are.
Instructor-led workshops and programsIn-house, virtual or blended10 languagesDelivered inEnglish, Spanish, Mandarin, German, Arabic, Portuguese, Hindi, French, Japanese, Italian100+ countriesWe have delivered inUnited States, United Kingdom, India, Canada, Germany, France, Netherlands, UAE, Saudi Arabia, Singapore, Australia, Japan, Brazil, South Africa and 90+ more countries





Trusted as a Leading Corporate Training Provider by
















What is corporate Data Engineering training?
Data engineering training is instructor-led group training that builds an organization's ability to move data reliably from source to insight. It spans pipeline development, lakehouse platforms, streaming, data modelling, and DataOps, taught against the platforms your teams actually run. Programs are scoped to your stack, from Spark and Databricks to Kafka, dbt, Informatica, and Microsoft Fabric, and delivered to a closed cohort rather than sold as individual seats.
The distinction that matters commercially is between tool training and pipeline capability. Knowing Spark syntax is not the same as running data products: tested pipelines, governed models, and on-call discipline that keep dashboards and AI fed with trustworthy data. Our programs build the second, with labs on real platforms and realistic data, so engineers leave able to operate what they built.
Programs split across the major practice areas. Spark, lakehouse and big data: PySpark, Databricks, Delta Lake, and Hadoop. Enterprise ETL: Informatica, IBM DataStage, and modernization paths to cloud. Cloud data platforms: Microsoft Fabric, BigQuery, and AWS data services. Data architecture and modelling, orchestration with Airflow and dbt, streaming with Kafka and Flink, and data quality and testing.
Every engagement starts with discovery: your platforms, your data pain, and which teams carry the pipelines. Trainers are then matched from a vetted bench of data engineers and architects, and the program is tailored before delivery. Cohorts are closed to your organization, run in your timezone, and measured with pre and post assessments so engineering leadership can see what changed.
Explore Data Engineering training by topic
Eight areas carry most of the catalog. Start where your data pain is greatest.
- Spark, Lakehouse & Big Data8 Instructor-led Programs
- Data Architecture & Modelling5 Instructor-led Programs
- Enterprise ETL Platforms5 Instructor-led Programs
- Orchestration, dbt & DataOps5 Instructor-led Programs
- Cloud Data Platforms4 Instructor-led Programs
- Data Quality & Testing2 Instructor-led Programs
Popular Data Engineering training programs
The most in-demand Data Engineering training programs enterprises book right now.
 Spark, Lakehouse & Big Data
Apache Beam
~ 24 HoursInstructor-ledInstructor-led training on Apache Beam, scoped to your team's level and use cases.
 Data Architecture & Modelling
Data Mesh & Streaming Architecture
~ 24 HoursInstructor-ledInstructor-led training on Data Mesh & Streaming Architecture, scoped to your team's level and use cases.
 Enterprise ETL Platforms
Azure Data Factory
~ 26 HoursInstructor-ledInstructor-led training on Azure Data Factory, scoped to your team's level and use cases.
 Orchestration, dbt & DataOps
Apache Airflow
~ 24 HoursInstructor-ledInstructor-led training on Apache Airflow, scoped to your team's level and use cases.
Instructor-led Data Engineering training programs by topic.
Browse all 37 data engineering programs across 9 topics, from Spark and lakehouse platforms to ETL, streaming, and cloud data services. Filter by topic and delivery format, then request a tailored proposal.
SHOWING 1–15 OF 37 · 37 IN THE LIVE CATALOG
Apache Airflow
Instructor-led training on Apache Airflow, scoped to your team's level and use cases.
Apache Beam
Instructor-led training on Apache Beam, scoped to your team's level and use cases.
Apache Hama
Instructor-led training on Apache Hama, scoped to your team's level and use cases.
Apache Hive
Instructor-led training on Apache Hive, scoped to your team's level and use cases.
Apache Iceberg for Data Lakehouse Engineering
Instructor-led training on Apache Iceberg for Data Lakehouse Engineering, scoped to your team's level and use cases.
Apache Pig
Instructor-led training on Apache Pig, scoped to your team's level and use cases.
AWS Glue
Instructor-led training on AWS Glue, scoped to your team's level and use cases.
Azure Data Factory
Instructor-led training on Azure Data Factory, scoped to your team's level and use cases.
CloverETL
Instructor-led training on CloverETL, scoped to your team's level and use cases.
Data Contracts & Data Quality Engineering
Instructor-led training on Data Contracts & Data Quality Engineering, scoped to your team's level and use cases.
Data Engineering & Analytics on Google Cloud (BigQuery)
Instructor-led training on Data Engineering & Analytics on Google Cloud (BigQuery), scoped to your team's level and use cases.
Data Engineering on AWS (Redshift, Glue & Lake Formation)
Instructor-led training on Data Engineering on AWS (Redshift, Glue & Lake Formation), scoped to your team's level and use cases.
Data Engineering with Apache Spark & Databricks
Instructor-led training on Data Engineering with Apache Spark & Databricks, scoped to your team's level and use cases.
Data Mesh & Streaming Architecture
Instructor-led training on Data Mesh & Streaming Architecture, scoped to your team's level and use cases.
Data Modelling for Analytics & AI
Instructor-led training on Data Modelling for Analytics & AI, scoped to your team's level and use cases.
Curated Learning Pathways for Your Teams
Build your team’s capabilities in Data Engineering with curated training programs arranged in a clear learning sequence. Each pathway builds skills progressively, helping your workforce achieve defined milestones and apply their learning to business goals.
- Data Contracts & Data Quality Engineering
Catches bad data before it reaches reports and AI models
- Dimensional Data Modeling
Designs data platforms and models that scale and stay usable for analytics and AI
- Data Contracts & Data Quality Engineering
- Apache Iceberg for Data Lakehouse Engineering
Processes large data sets efficiently on Spark and open lakehouse formats
- Apache Beam
Processes large data sets efficiently on Spark and open lakehouse formats
- Hadoop Administration & Development
Processes large data sets efficiently on Spark and open lakehouse formats
- Apache Iceberg for Data Lakehouse Engineering
- DataOps & Pipeline Reliability
Runs pipelines on schedule, transforms data with tested code, and keeps it reliable
- Data Contracts & Data Quality Engineering
Catches bad data before it reaches reports and AI models
- ETL Testing
Catches bad data before it reaches reports and AI models
- DataOps & Pipeline Reliability
- Event Streaming with Apache Kafka
Moves and processes data in real time for operational and analytics use
- Data Mesh & Streaming Architecture
Designs data platforms and models that scale and stay usable for analytics and AI
- Event Streaming with Apache Kafka
- Modern Data Architecture & Data Mesh
Designs data platforms and models that scale and stay usable for analytics and AI
- Data Modelling for Analytics & AI
Designs data platforms and models that scale and stay usable for analytics and AI
- Denodo
Designs data platforms and models that scale and stay usable for analytics and AI
- Data Contracts & Data Quality Engineering
Catches bad data before it reaches reports and AI models
- Modern Data Architecture & Data Mesh
- Informatica (PowerCenter & IDMC)
Maintains and modernizes enterprise ETL estates
- Informatica IDMC Cloud Data Integration
Maintains and modernizes enterprise ETL estates
- Hadoop Administration & Development
Processes large data sets efficiently on Spark and open lakehouse formats
- ETL Testing
Catches bad data before it reaches reports and AI models
- Informatica (PowerCenter & IDMC)
Find the Right Data Engineering Training for Your Teams
Explore Data Engineering training aligned with your teams’ functions, job roles, industry and tools. Help your teams build the knowledge and practical skills to apply data engineering across your organization, supporting your business priorities and evolving needs.
Data Integration Teams
Define source-to-consumer contracts, ownership and change handoffs across enterprise systems. Align engineering, operations and data owners around freshness, quality and incident expectations.
Analytics & BI Teams
Turn raw operational data into reusable models for business reporting. Strengthen transformation logic, data validation and handoffs so different reports use consistent definitions.
AI & Machine Learning Teams
Prepare reproducible datasets for model development and ongoing inference workflows. Address freshness, quality and pipeline dependencies before data issues reach model consumers.
Data Platform Operations
Operate shared processing environments with visibility into failures and resource use. Establish runbooks, monitoring and recovery practices for business-critical data workloads.
Data Engineers
Build pipeline implementation skills through SQL, Python and distributed-processing exercises. Practice writing, testing and debugging transformations so individual engineers can maintain production-quality code.
Data Architects
Evaluate storage, processing and integration patterns against analytical and operational requirements. Make explicit tradeoffs around latency, interoperability and maintainability before teams commit to a platform design.
Databricks Practitioners
Develop batch and streaming data workflows on a lakehouse platform. Apply ingestion, transformation and operational practices that make downstream analytical data easier to maintain.
Microsoft Fabric Practitioners
Connect lakehouses, notebooks and pipelines into a consistent data workflow. Learn how processing choices and data organization affect downstream analysis and team handoffs.
Apache Spark Practitioners
Transform large datasets through SQL and DataFrame-based processing. Build practical judgment around streaming, execution performance and deployment rather than treating every workload the same.
Banking Data Teams
Build traceable data flows across fragmented banking systems and reporting needs. Improve aggregation quality and timeliness while preserving clear ownership and evidence of controls.
Training a role that is not listed, or a mix of them? Tell us who you are training and what they need to do, and we build the shortlist.
Categories worth exploring next
Where data engineering teams most often cross-train, based on how these courses are classified.
Capabilities your organization will gain.
Domain-level outcomes, not course objectives. These are the capabilities enterprises usually buy this training to build.
Engineer reliable data pipelines
Build pipelines that ingest, transform, and serve data on schedule, with retries, lineage, and monitoring built in.
Operate Spark and lakehouse platforms
Run Spark and Databricks workloads in production: tuning, partitioning, and lakehouse patterns that scale.
Stream data in real time
Move events with Kafka and Flink: exactly-once semantics, schema evolution, and backpressure handled.
Model data that lasts
Model data for analytics and AI: dimensional models, data mesh domains, and contracts that hold.
Orchestrate and operate with DataOps
Automate with Airflow and dbt, and run DataOps practices that catch breakage before stakeholders do.
Modernize legacy data estates
Modernize Informatica, DataStage, and Hadoop estates onto cloud and lakehouse platforms without breaking production.
Ship trusted, governed data
Embed contracts, tests, and observability so every dataset ships with a trust guarantee.
Instructor-led Training Delivery: You pick the format
Onsite, live virtual, or hybrid, every program is instructor-led and built around your teams.
In-house / On-Site Session
A trainer comes to your office and works face to face with your team, using your policies and your examples.
- In-person, classroom based training at your own premises
- Tailored to your policies, data and use cases
- Hands-on, high-interaction sessions
- Team builds shared context together
- Schedule set around your operations
For small teams or enterprise-wide training, across one site or multiple global locations, in one language or multiple languages.
Get a Quote
Virtual / Online Session
Expert-led live online sessions delivered anywhere, with consistency and easy scheduling. Training tools such as Zoom or Microsoft Teams are selected subject to your organization's approval and compliance requirements.
- Delivered anywhere worldwide
- Standardized content for consistent outcomes
- Join from your own workspace, no travel
- Scales to large groups across sites
- Interactive tools keep remote learners engaged
For small teams or enterprise-wide training, across one site or multiple global locations, in one language or multiple languages.
Get a Quote
Blended / Hybrid Session
Combine in-person sessions with live online training in a coordinated instructor-led program, with the mix planned around your team's needs.
- A planned mix of classroom based and online sessions
- In-person practice with live virtual reinforcement
- One learning plan across both delivery formats
- Online sessions using organization-approved tools
- Session sequence and schedules agreed with your team
For small teams or enterprise-wide training, across one site or multiple global locations, in one language or multiple languages.
Get a Quote
Learn from Trainers with Industry Experience
Equip your teams with practical skills in data engineering through trainers who bring relevant industry knowledge and real business examples to every session. Our trainers connect data pipelines, data modeling, and stream processing to workplace challenges, helping employees apply what they learn with confidence.
Dr. UmaPavan
Big Data and Hadoop Trainer in Hyderabad
16+ years of Experience
Mahanthaswamy
Azure Trainer in Bengaluru
8+ years of Experience
Ramananda
MEAN Full Stack Trainer in Bengaluru
12+ years of Experience
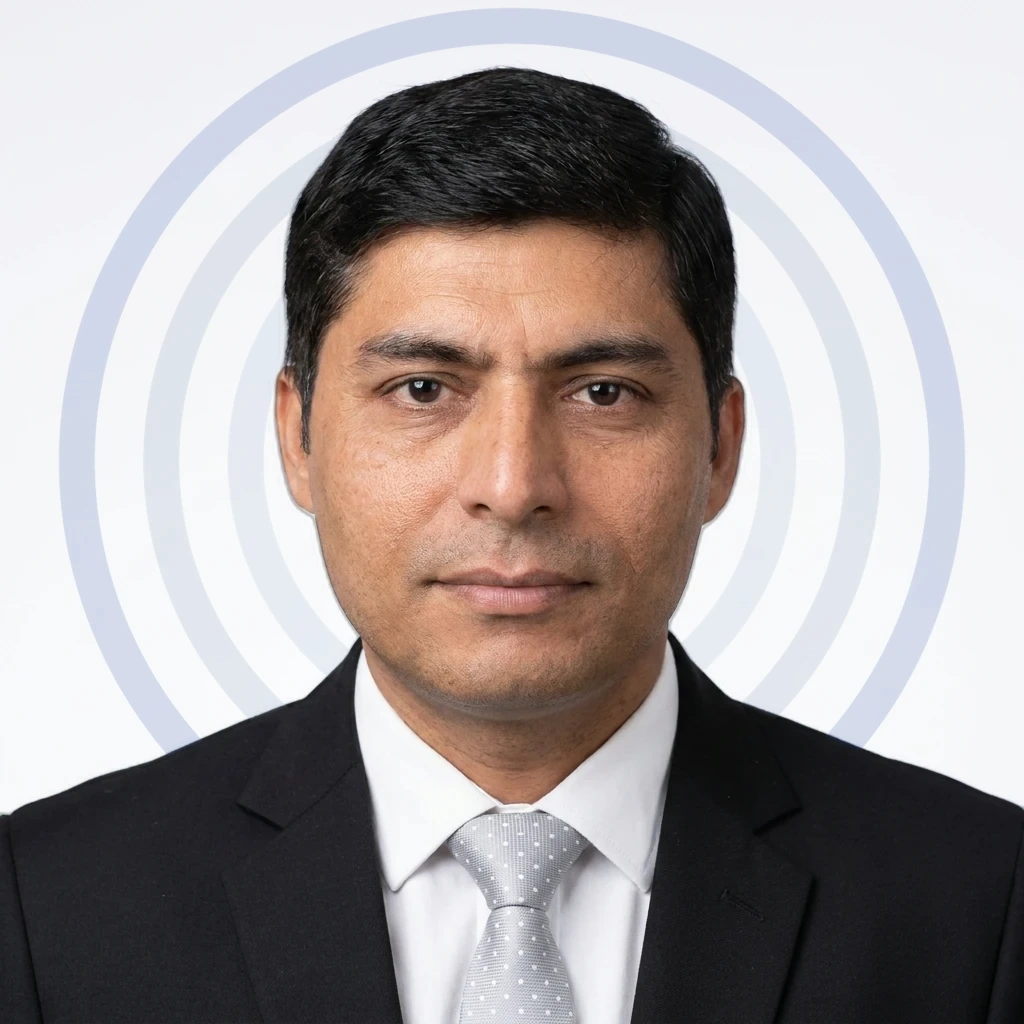
Hitesh
Big Data Hadoop Trainer in New Delhi
9+ years of Experience
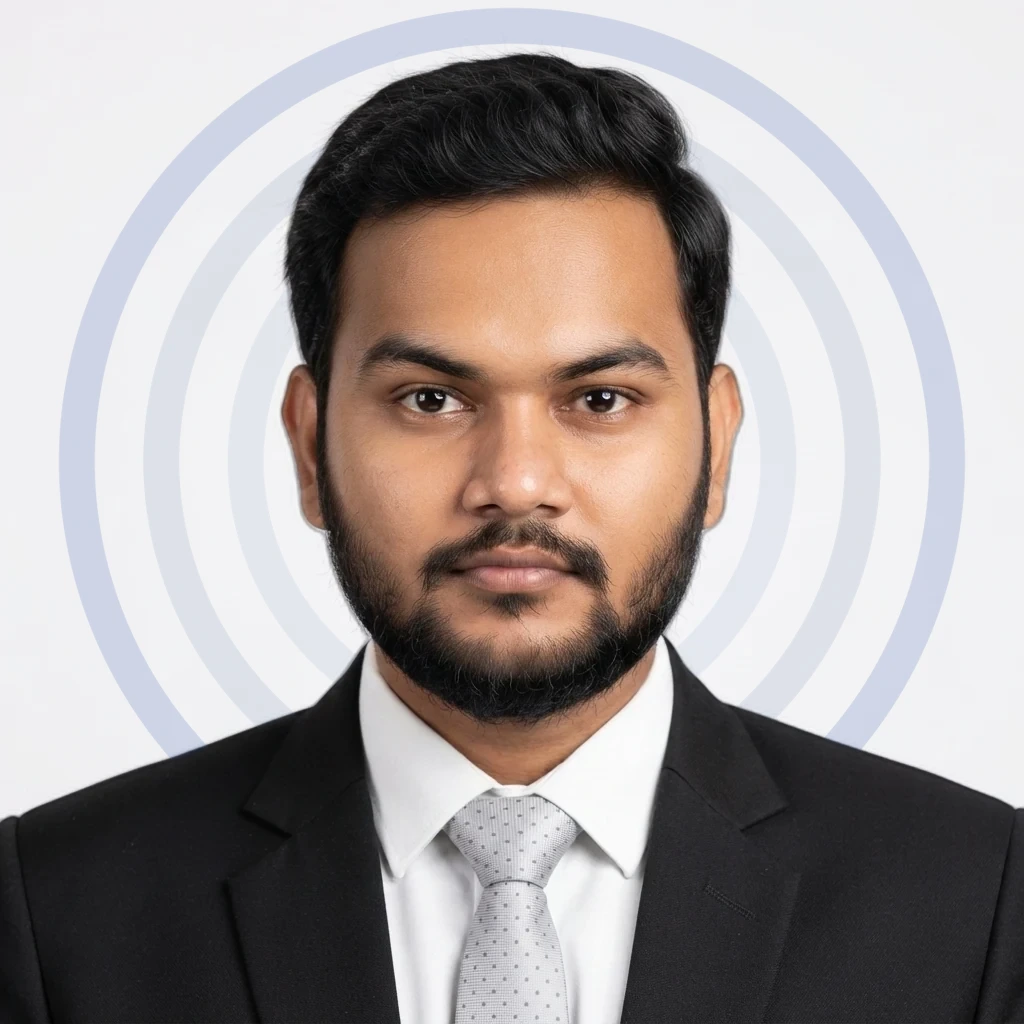
Burhan
Cloud SQL & NoSQL Trainer in Bengaluru
11+ years of Experience
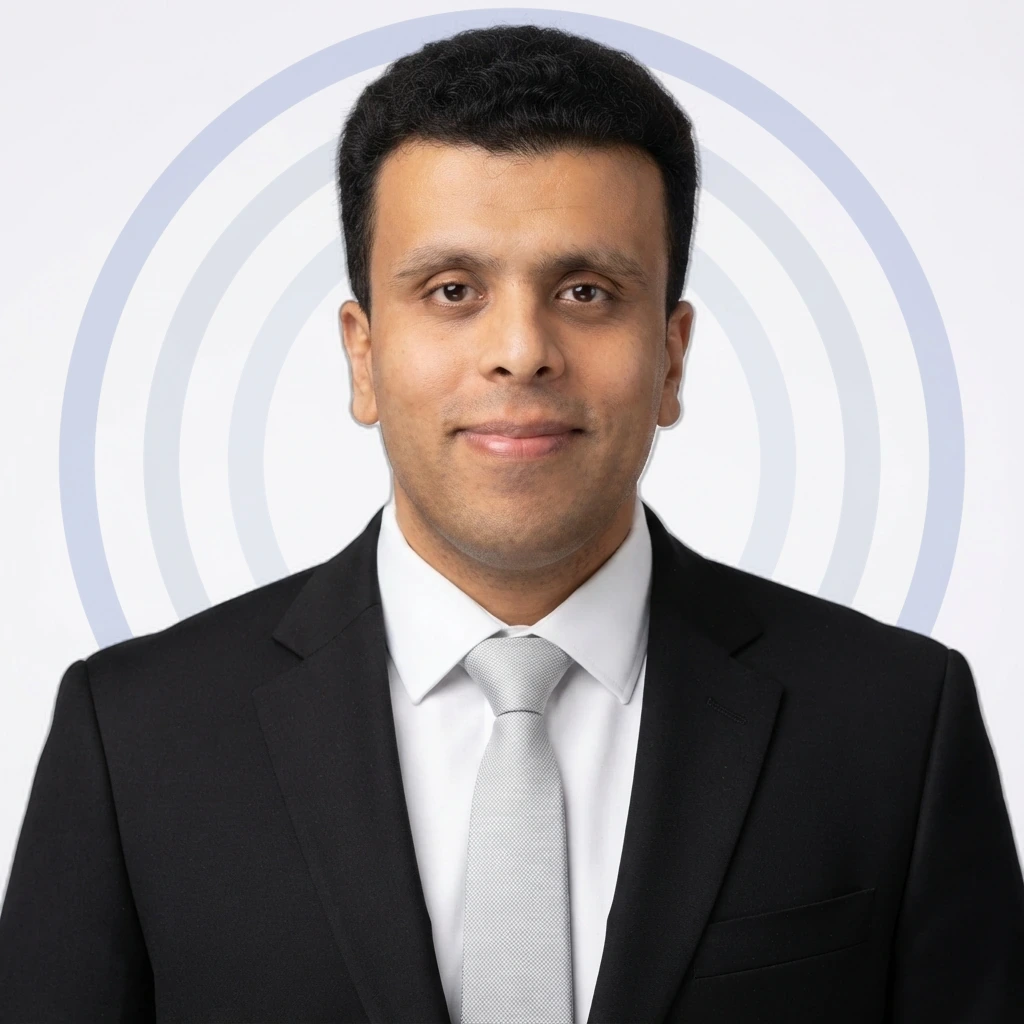
Amit
Spark Developer Trainer in Greater Noida
10+ years of Experience
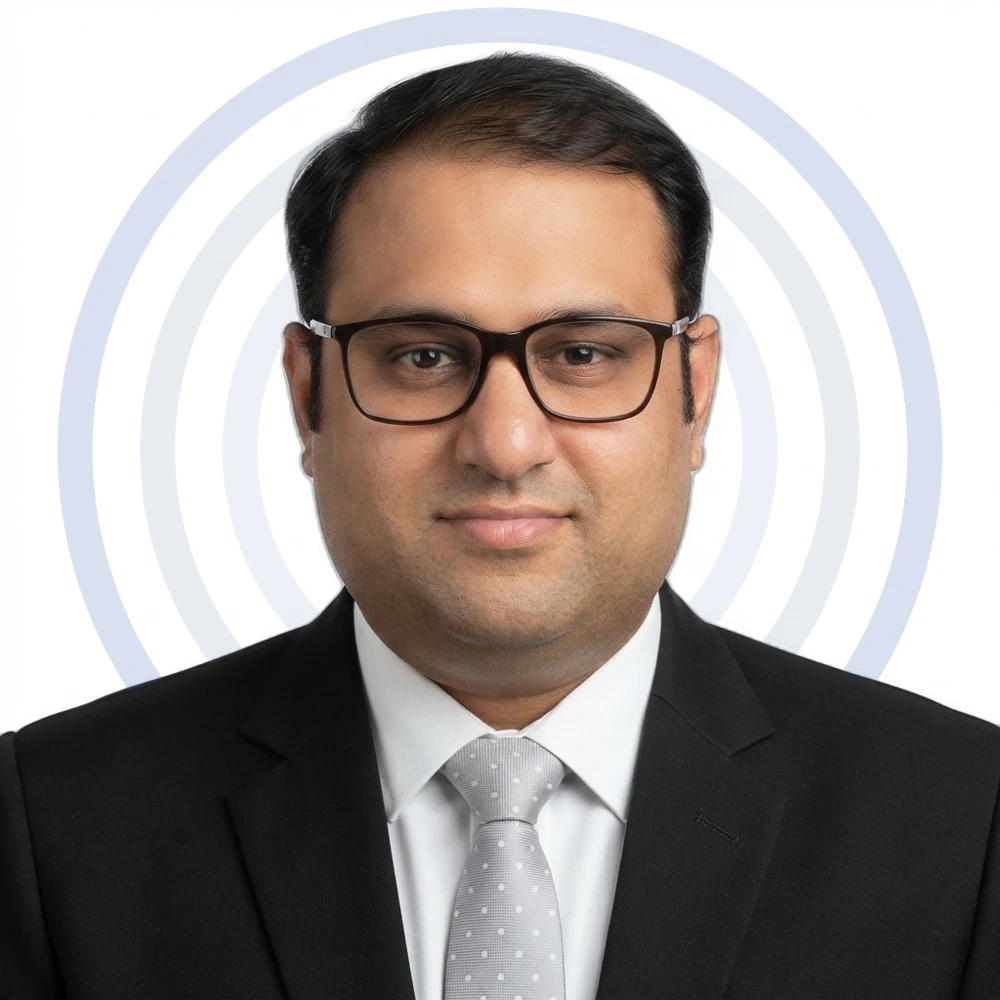
Virendra
Big Data Hadoop Trainer in Pune
11+ years of Experience
Trainers are matched to your stack and delivery window at scheduling. We confirm your assigned trainer, with a full profile, before the program is booked, and you can sit in on a trial session first.
Why enterprises choose Edstellar as their Data Engineering training provider.
Edstellar helps data teams turn fragmented sources into dependable data products. Our role-based, instructor-led training is customized for engineers, architects and platform teams, connecting pipeline design, data modeling and orchestration with business requirements. Practical exercises develop judgment around reliability, access and processing tradeoffs, while adaptable learning supports new architectures, changing data volumes and the needs of downstream users across the enterprise.

Practice moving and transforming data around real consumption needs
Align engineers, architects and platform teams on shared delivery challenges
Evaluate quality checks, failure recovery and access throughout pipelines
Explore processing patterns as sources, scale and requirements change
Training experience across industries informs practical data engineering learning
Company-wide delivery experience informs learning for data platform teams
Company-wide trainer network connects data engineering with complementary disciplines
Edstellar's certified quality and information-security management systems underpin data engineering training delivery
How a Data Engineering capability program actually runs.
Every engagement runs the same five stages, from capability baseline through delivery to sustained measurement.
Discover
We meet your stakeholders and L&D team to baseline what your people can do today against the Data Engineering capability you need.
Week 1-2
Design
Programs are assembled against your policies, obligations, and team levels, then trainers are shortlisted from the vetted bench.
Week 2-4
Deliver
Closed-cohort instructor-led sessions in your language and timezone, with labs, exercises, and materials shipped alongside.
Scheduled to your calendar
Assess
Pre and post assessments establish a measurable change in capability, benchmarked against role frameworks.
Immediately after delivery
Sustain
Retrospectives, refresher modules and skill-refresh tracking keep the investment from decaying, and the measured gaps feed the next cycle.
Quarterly
Stage 05 feeds the next cycle: the gaps it measures become the next Discover.
Also from Edstellar
Talent assessments
→Psychometric, behavioral, leadership and 360-degree assessment.
Training needs analysis
→Needs analysis, gap identification, and a training roadmap.
L&D consulting
→Learning strategy, content, technology and ROI measurement.
OD consulting
→Org design, succession planning and cultural change.
Managed training services
→Training outsourcing, vendor management, logistics and administration.
Coaching solutions
→Executive and manager coaching that keeps skills in use.
Questions enterprises ask before booking.
Data engineers, analytics engineers, data architects, platform engineers, BI teams, and engineering leaders. A foundations track covers teams new to the discipline.
Instructor-led and live, as a closed cohort for your team, on-site or virtually. Labs run on real data platforms and pipelines, not slides. You choose the format, schedule, and timezone.
Yes. Programs are tailored to the platforms you run: Spark, Databricks, Kafka, dbt, Informatica, DataStage, Microsoft Fabric, and the cloud data services. Tell us your stack in the discovery call.
Most programs run 16 to 32 hours across several sessions. Platform programs like Databricks and Fabric follow the tool syllabus; bundles and rollouts are scheduled around your calendar.
Cohorts run from a single team of 8 up to enterprise rollouts of hundreds, with one trainer per cohort for hands-on lab quality.
Yes. Every program includes labs on live environments: pipelines you build, lakehouses you query, and streams you operate. Exercises use realistic data scenarios.
Pre and post assessments benchmark each participant against role frameworks, with a completion report showing measured change per cohort.
Yes. Labs and case studies can run against your pipeline definitions, schemas, and data quality rules, so teams train on their reality.
Yes. Programs align to Databricks, Microsoft Fabric, and AWS data paths, with exam-style labs and practice assessments built in.
Yes. Dedicated tracks cover data contracts, testing, observability, and governance so pipelines stay trustworthy in production.
Yes. Migration tracks cover moving Informatica, DataStage, and Hadoop estates to cloud and lakehouse platforms without breaking production.
A room or virtual setup, participant list, and access details for lab environments. We ship lab guides, exercises, and completion evidence.
Discovery to delivery typically takes two to four weeks, depending on customization depth and trainer matching for your stack.
Yes. You can sit in on a trial session with the shortlisted trainer before committing, to check fit with your team and level.
Start a Request for Proposal (RFP) shaped to your needs.
Pick the scale that matches your rollout. Every quote is tailored to your teams and timeline.
Team size
1-25 PARTICIPANTS
Single cohort
One or two programs for a single team, delivered as a closed cohort. The usual entry point for a first Data Engineering engagement.
- One cohort of up to 25 participants
- Curriculum customized to your obligations
- Onsite, virtual, or offsite delivery
- Certificates and completion report
26-150 PARTICIPANTS
Scaled cohort
Multiple cohorts or programs for larger teams, with delivery structured around your workforce and training requirements.
- Multiple cohorts across teams
- Curriculum customized to your obligations
- Onsite, virtual, or offsite delivery
- Certificates and completion reporting
151-1,000 PARTICIPANTS
Enterprise rollout
A coordinated rollout across business units, with role-based tracks and central reporting for L&D.
- Enterprise-wide cohort planning
- Role-specific curriculum options
- Flexible scheduling across regions
- Program governance and reporting
1,000+ PARTICIPANTS
Global scale
Data Engineering capability at organizational scale, with dedicated management and measurement from pilot to rollout.
- Global delivery at scale
- Dedicated program management
- Custom curriculum and assessments
- Executive reporting and ROI tracking
Ask us about Data Engineering training for your teams.
Tell us which teams you are training and what they need to be able to do. Anything you filtered in the catalog comes through with your message.