HBase, Impala and Flume Corporate Training
Move big data from stream to insight.
This instructor-led corporate training builds real big data engineering skills: ingesting with Flume, modeling in HBase, and analyzing with Impala SQL, all practiced in guided hands-on labs on realistic data workloads.
Instructor-led group trainingVirtual / on-site / hybrid10+ languagesDelivered in English, Spanish, Mandarin, German, Arabic, Portuguese, Hindi, French, Japanese, Italian, and more100+ countriesWe have delivered in United States, United Kingdom, India, Canada, Germany, France, Netherlands, UAE, Saudi Arabia, Singapore, Australia, Japan, Brazil, South Africa and 90+ more countries
How we build a big data pipelines team
The Edstellar BIG DATA ENGINEERING Capability Model
Assess
We baseline your team's big data engineering skills before training begins.
Learn
Instructor-led sessions build HBase, Impala & Flume knowledge step by step.
Practice
Guided hands-on labs lock in each technique with coaching.
Apply
Teams apply HBase, Impala & Flume to real work before the program ends.
Measure
Skill checks show what improved and what comes next.
 Expert trainers
Need more than one program?Get a group quote
Trusted as a Leading Corporate Training Provider by




HBase, Impala and Flume Training for Employees: Program Overview
HBase, Impala, and Flume form a classic big data stack: Flume streams data in, HBase stores it at scale, and Impala queries it with SQL speed. This program teaches your team to design, operate, and tune all three together.
Led by data engineers who run these workloads in production, the program moves from Flume ingestion to HBase data modeling to Impala analytics and performance tuning. Every module includes guided hands-on labs where your team builds and tunes real pipelines on realistic data volumes.
The program closes with a capstone full build: an integrated data pipeline streaming through Flume into HBase and queried with Impala, reviewed by the instructor.
Teams leave able to design Flume topologies, model HBase tables for access patterns, write fast Impala SQL, and operate the full stack with confidence.
What's Included in this Workshop for Your Enterprise Teams
- 1
Instructor-Led Delivery
Live Hadoop tools sessions with certified trainers
- 2
Hands-On Labs
Guided labs built on real-world use cases
- 3
Tailored Curriculum
Agenda tuned to your stack and team goals
- 4
Assessments & Materials
Pre and post checks plus reference workbooks
- 5
Post-Training Support
Follow-up help as teams apply the skills
- Instructor-led delivery: onsite, live virtual, or hybrid
- Tailored agenda: topics matched to your team's stack and goals
- Guided hands-on labs built around real-world use cases
- Cohort sizes that suit small teams and large groups
- Materials, workbooks, and post-program reference guides
- Post-training support and assessment on request
Build your team's skills. Anywhere in the world.
Real-world use cases
from day one
Instructor-led training
for your teams
Delivered globally
in 100+ countries
Enterprise Training Solutions Customized for Your Company
One partner for instructor-led corporate training, delivered the way your teams work.
Request a Training Quote- Customized Training Delivery
- Scale Your Training: Small to Large Teams
- In-person Onsite, Live Virtual or Hybrid Training Modes
- Plan from 2000+ Industry-ready Training Programs
- Guided Technical Labs, Led by Industry Experts
HBase, Impala and Flume Course Topics and Program Outline
6 modules, 24 instructor-led hours, and 3 guided labs that move HBase, Impala & Flume from theory to dependable team practice.
Built by Edstellar with data engineers who run HBase, Impala, and Flume workloads in production
Built by data engineers who run HBase, Impala, and Flume workloads in production, shaped around your stack and use cases.
We check where your team stands on Hadoop tools today, so the program targets real gaps instead of repeating what they know.
Instructor-led sessions teach big data engineering concepts in order, with demos and Q&A in every module.
Guided labs give your team coached repetition on realistic big data engineering scenarios with instructor review.
The capstone full build proves the learning: an integrated HBase and Impala pipeline, built, reviewed, and ready to take back to work.
From baseline to job-ready in 24 hours.
Delivered as
Cohorts run hybrid, onsite, or live virtual formats, scheduled around your calendar in half-day or full-day blocks.
Map data flows for sample use cases.
learnHadoop ecosystem roles
Flume, HBase, Impala overview
Data flow architecture
Use case patterns
Build a Flume topology ingesting log data.
learnFlume agent architecture
Sources, channels, sinks
Reliable ingestion patterns
Multi-agent topologies
Design HBase schemas for access patterns.
practiceRow key design
Column families
Access pattern modeling
Avoiding hotspotting
Tune and monitor a loaded HBase cluster.
practice_hfRegion splits and balancing
Compactions and tuning
Bulk loading patterns
Monitoring HBase health
Write and tune Impala queries on big data.
practiceImpala SQL essentials
Parquet and file formats
Partitioning strategies
Query tuning
Build and tune an end-to-end pipeline.
applyPipeline design
Integration and testing
Performance validation
Instructor review
Customize This Program Tailored to Your Team?
Tell us your training needs: what your team already works with, the level they’re at, and the topics you want them to focus on. We’ll adjust the modules, duration and hands-on labs, and send you a customized outline for your group.
Key Skills and Outcomes Your Team Will Gain
Your team will build Flume ingestion topologies, model HBase tables for access patterns, operate HBase clusters, and write fast Impala SQL over big datasets.
Big data architecture
Explain how Flume, HBase, and Impala fit together in data flows.
Flume topologies
Build reliable multi-agent ingestion pipelines.
HBase modeling
Design row keys and schemas for real access patterns.
HBase operations
Manage regions, compactions, and bulk loads in production.
Impala SQL
Write analytical SQL over Parquet and partitioned data.
Query tuning
Tune Impala queries and file layouts for speed.
Pipeline ownership
Operate the full stack with monitoring and confidence.
Teams that Benefit from this HBase, Impala and Flume Group Training
Built for data engineers and Hadoop developers who build big data pipelines. Content adapts to each cohort's data volumes and use cases, so teams practice on the workloads they actually run.
Engineers building big data pipelines
Data engineers who move and store data get Flume, HBase, and Impala practice on realistic volumes.
Workflow friction
- Slow ingestion
- Hotspotting in HBase
- Sluggish analytical queries
How the program helps
- Build reliable ingestion
- Model to avoid hotspots
- Tune queries for speed
Practice use cases
- Flume
- HBase modeling
- Impala tuning
- pipelines
Analysts querying big data
Analysts and BI developers who query Hadoop data get Impala SQL and file-format practice for fast analytics.
Workflow friction
- Slow Hive queries
- Poorly partitioned data
- Unclear file formats
How the program helps
- Write fast Impala SQL
- Partition effectively
- Choose right formats
Practice use cases
- Impala SQL
- partitioning
- Parquet
- tuning
Platform engineers running clusters
Platform engineers who operate the stack get HBase operations and monitoring practice for healthy clusters.
Workflow friction
- Unbalanced regions
- Runaway compactions
- Blind spots in monitoring
How the program helps
- Balance regions
- Tune compactions
- Monitor effectively
Practice use cases
- regions
- compactions
- monitoring
- bulk loads
Groups run with employees at similar levels so exercises match daily work. Mixed cohorts are welcome when goals align.
Prerequisites: Participants get the most from this program with data engineering or Hadoop experience. Each tool is taught from foundations, so mixed-experience cohorts work well. Content adapts to each cohort's data and use cases, and the discovery call tunes the depth to your team.
HBase, Impala & Flume: skill progression
A realistic path from foundation to advanced big data engineering capability, mapped to the modules above. Your team can see exactly which skills each module builds.
Bands show where each skill starts and where this program takes it.
Different Teams, Locations, Time Zones, or Languages? We've Got You Covered.
Whether your teams are spread across countries, time zones, languages, or experience levels, we deliver tailored training programs that ensure a consistent learning experience across your global workforce.
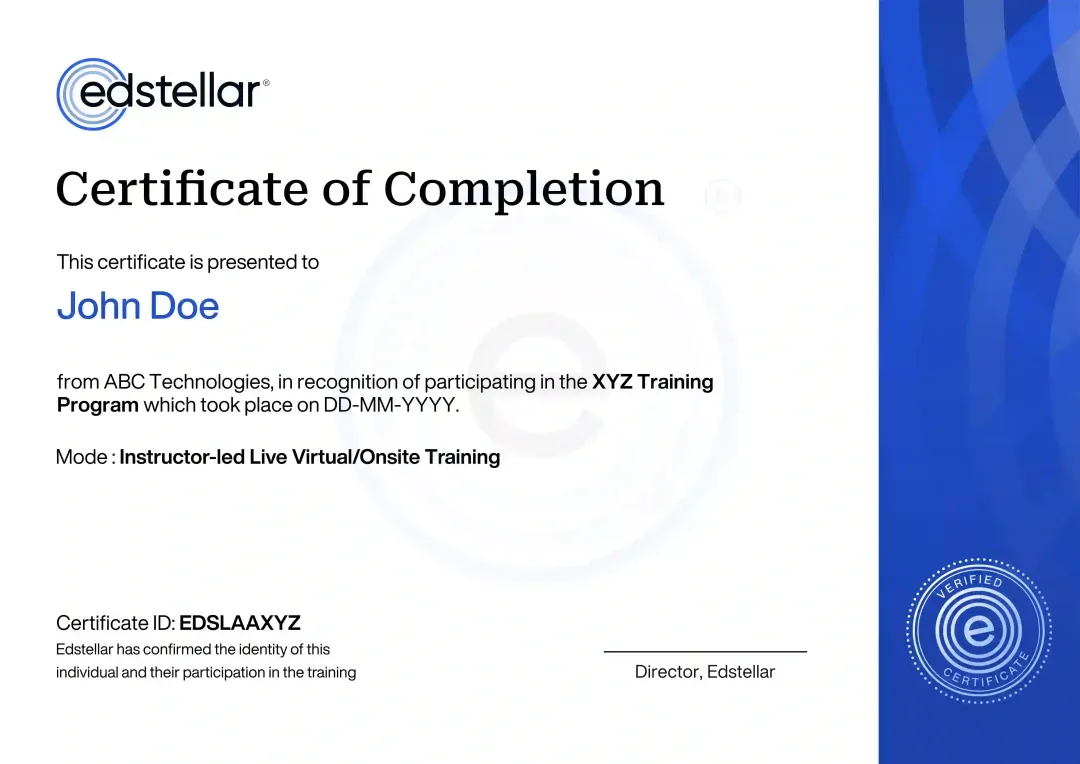
Certificate of Training Completion.
On successful completion, employees receive an Edstellar course completion certificate, recognizing their commitment to ongoing learning and professional development. It validates the skills they have built and motivates them to keep growing and contribute to organizational success.
Earned, not attended. Awarded on completion of all hands-on labs and the capstone project.
Training Delivery Modes: Onsite, Virtual and Hybrid
Instructor-led delivery in onsite, live virtual, or hybrid formats, with hands-on labs in every session.
HBase, Impala & Flume Onsite Training
Your trainer comes to your premises. Sessions stay practical: hands-on labs run in the room with the instructor beside each team.
- Trainer at your premises
- Guided guided labs with the instructor beside each team
- Team collaboration in one room
- Agenda tuned on the spot
HBase, Impala & Flume Live Virtual Training
Join from anywhere in live instructor-led sessions. Labs run in shared environments so the trainer can see every screen and coach in real time.
- Join from anywhere, live
- Shared lab environments with trainer coaching
- Sessions recorded for review
- Same curriculum, same hours
HBase, Impala & Flume Hybrid Training
Split your cohort between the training room and a live virtual feed. Every session is instructor-led, with hands-on labs in each module and the same curriculum for both groups.
- Live instruction in every session
- Onsite workshops for guided labs
- Virtual sessions for distributed teams
- One cohort or split batches
Need a Customized Training Format That Works for Your Team?
Our training delivery is customized to your team's schedule, full days, half days, sessions spread across weeks, or modular formats. Share your preferred timeline, and we'll plan the training around it.
Frequently Asked Questions
Edstellar teaches Flume, HBase and Impala as parts of one data workflow. Teams connect streaming ingestion, storage and SQL analysis in an integrated pipeline. This helps data engineers understand the handoffs and failure points between the tools rather than relying on separate product knowledge.
The published baseline is 24 hours. The course connects subject knowledge with applied work across big data stack overview and flume ingestion. The practical sequence culminates in work on an integrated data pipeline streaming through Flume into HBase and queried with Impala. Edstellar coordinates curriculum adaptation, trainer matching and delivery so L&D can run the program consistently across cohorts.
Edstellar brings HBase, Impala & Flume training to enterprise teams through a network of 5,000+ vetted trainers and coaches, built on work with 200+ enterprise clients in 100+ countries. Developed with big data engineers, it focuses on HBase, Impala, Flume and data ingestion. Each cohort gets a trainer screened for subject expertise, industry experience and facilitation quality, whose profile you can review before confirming. Delivery is onsite, virtual or hybrid, with pre- and post-training assessments.
Compare providers on the depth of practical work in Flume ingestion, HBase storage and Impala querying, not the number of topics listed. Edstellar combines instructor-led application with pre- and post-training assessments and a post-training report. Review the proposed trainer, exercises and expected outputs against the responsibilities of your team, then compare the complete delivery scope and cost.
Edstellar matches the trainer to the curriculum and participants’ working context. Your organization can review the proposed profile and discuss relevant experience before confirming. For this course, look for applied experience in Flume ingestion, HBase storage and Impala querying, together with the ability to explain decisions and give useful feedback to your cohort. Confirm any language or industry requirements during trainer selection.
Question Not Answered Here?
Put it in the request. A training specialist answers it directly, within one business day.
Where this Training Fits in Your Team's learning path.
HBase, Impala and Flume extend a Hadoop cluster, so your team should run Hadoop and query it with Hive first. With those tools in hand, the last step is securing the cluster that now holds more data and serves more users.
RUN HADOOP
Hadoop Administration & Development Training
Install and manage a Hadoop cluster and HDFS, the base the other tools run on.
QUERY WITH HIVE
Apache Hive Training
Query cluster data with HiveQL before moving to faster and real-time options.
HBASE, IMPALA AND FLUME
HBase, Impala & Flume Training
Store data in HBase, query it fast with Impala, and ingest streams with Flume.
SECURE HADOOP
Hadoop Security Training
Secure the expanded cluster with authentication, authorisation and encryption.
More related courses
Apache HBase Training
Event Streaming with Apache Kafka Training
PySpark Training
Why Choose Edstellar as Your HBase, Impala and Flume Corporate Training Provider
Edstellar delivers HBase, Impala & Flume as instructor-led corporate training for enterprise teams: practitioner instructors, hands-on labs, and a curriculum tailored to your goals.
EXPERT TRAINERS
YEARS DELIVERING
ORGANIZATIONS TRAINED
CERTIFIED
Tailored
Hadoop tools training scoped to your stack and team level, tuned module by module after a discovery call.
Proven Methodology
A Learn-Practice-Apply arc refined across thousands of corporate teams: concepts first, then guided labs until each skill holds.
Practice-Based Learning
Most hours go to doing: guided labs on realistic tasks your team faces on the job, with instructor review after each one.
Expert Trainers
Instructors who work in big data engineering teach from real delivery experience, matched to your cohort and goals.
Global Scale
Same Hadoop tools program for every cohort, delivered across time zones by 5,000+ certified trainers.
Measurable Outcomes
Pre- and post-program assessments mapped to your curriculum, so you can see exactly what each cohort learned and what comes next.
Connect Flume Ingestion, HBase Storage and Impala Analytics in Practice
Edstellar develops big-data pipeline capability by connecting ingestion, access patterns, and analytical queries. Participants build Flume flows, design and operate HBase tables, and examine Impala performance before integrating the tools. The final pipeline is reviewed for coherent data movement, justified modeling choices, and evidence that tuning addresses the workload's actual behavior.
- Step 01
Consult
We assess data-engineering and Hadoop experience, identifying gaps in log ingestion, HBase access-pattern design, or the interpretation of Impala query-performance problems.
- Step 02
Plan
Stack architecture leads into Flume ingestion, HBase modeling and operations, and Impala analytics before the complete end-to-end pipeline is built and tuned.
- Step 03
Align
We align big-data engineering expertise with platform and pipeline responsibilities, confirming suitable practice services and support for participants new to individual tools.
- Step 04
Customize
Sample logs, access patterns, and analytical questions reflect familiar data workloads, enabling topology and schema comparisons without exposing sensitive operational or customer records.
- Step 05
Execute
Participants configure ingestion, tune HBase workloads, and refine Impala queries, receiving feedback on data-flow integrity, storage decisions, monitoring, and the evidence behind performance changes.
- Step 06
Evaluate
We assess the pipeline for working ingestion and analytical access, justified HBase schema choices, appropriate monitoring, and clearly documented workload and query-tuning results.
Also from Edstellar
Talent assessments
Psychometric, behavioral, leadership and 360-degree assessment.
→Training needs analysis
Needs analysis, gap identification, and a training roadmap.
→L&D consulting
Learning strategy, content, technology and ROI measurement.
→OD consulting
Org design, succession planning and cultural change.
→Managed training services
Training outsourcing, vendor management, logistics and administration.
→Coaching solutions
Executive and manager coaching that keeps skills in use.
Start an RFP shaped to your needs.
Answer three quick questions about team size, scope, and how often you need the program run, then send the request from the last step. Everything you choose travels with it, so you only fill this in once.
How many team members need training?
HBase, Impala & Flume Training Packages & Pricing
Where L&D holds an annual budget, license packages price the whole year at once instead of raising a purchase order per workshop. Hours and licenses are pooled across teams, programs and locations, so unused capacity is not stranded in one department.
Starter
120
trainee licenses64 hours of group training
Tailored for SMBs
Growth
320
trainee licenses160 hours of group training
Ideal for growing SMBs
Enterprise
800
trainee licenses400 hours of group training
Designed for large corporations
Custom
Unlimited
trainee licensesDuration set by the rollout
Multi-region and multi-year
Training Packages & Pricing
Choose the training format that works for your team. Pricing is customized based on your requirements, cohort size, and delivery needs.
Request a Quote for HBase, Impala and Flume Training for Your Team
Tell us your team size, timelines, and goals for HBase, Impala & Flume training. An advisor will shape the agenda, confirm availability, and share a detailed proposal.